Blogs
2026
Spinning the Data Flywheel: From Curation to Fleet (opens in a new tab)
The stages that turn labeled data into a model on the road—curation, scenarios, data loading, training, and evaluation—and the challenges each raises at scale.
Physical AIModel TrainingLanceOctober 28, 2026appliedintuition.com
2025
Apache Hudi 2025: A Year In Review (opens in a new tab)
A look back at Apache Hudi in 2025: releases, community growth and ecosystem milestones.
Apache HudiDecember 29, 2025hudi.apache.org
Maximizing Throughput with Apache Hudi NBCC: Stop Retrying, Start Scaling (opens in a new tab)
Learn how Hudi's Non-Blocking Concurrency Control eliminates retry storms for concurrent writers, maximizing throughput in streaming and mixed workloads.
Apache HudiConcurrency ControlStream ProcessingDecember 16, 2025hudi.apache.org
Apache Hudi 1.1 is Here—Building the Foundation for the Next Generation of Lakehouse (opens in a new tab)
Apache Hudi 1.1 release highlights: partitioned record-level index, Flink writer overhaul, and foundations for the next generation of the lakehouse.
Apache HudiApache FlinkIndexingNovember 25, 2025hudi.apache.org
Deep Dive Into Hudi's Indexing Subsystem (Part 2 of 2) (opens in a new tab)
Advanced indexing in Apache Hudi: record and secondary indexes for point lookups, expression indexes, and async indexing that never blocks writes.
Apache HudiIndexingNovember 12, 2025hudi.apache.org
Deep Dive Into Hudi's Indexing Subsystem (Part 1 of 2) (opens in a new tab)
Inside Hudi's indexing subsystem: files, column stats and bloom filter indexes in the metadata table.
Apache HudiIndexingOctober 29, 2025hudi.apache.org
Partition Stats: Enhancing Column Stats in Hudi 1.0 (opens in a new tab)
How partition stats in Hudi 1.0 extend column stats to prune entire partitions at query planning time, speeding up selective queries.
Apache HudiIndexingOctober 22, 2025hudi.apache.org
Apache Kafka (Kafka Connect) vs. Apache Flink vs. Apache Spark: Choosing the Right Ingestion Framework (opens in a new tab)
This article compares three data ingestion frameworks—Kafka, Flink, and Spark—highlighting their unique strengths, use cases, and performance capabilities.
Apache KafkaApache FlinkApache SparkStream ProcessingOctober 3, 2025onehouse.ai
How to Save Apache Iceberg from Chilly Meltdown When Dimensions Too Hot to Handle (opens in a new tab)
Fast-changing dimension tables expose bottlenecks in Iceberg's design. How Apache Hudi, built for mutable writes, handles them instead.
Apache HudiApache IcebergData LakehouseSeptember 26, 2025onehouse.ai
Automatic Record Key Generation in Apache Hudi (opens in a new tab)
How Apache Hudi automatically generates record keys, and when to rely on auto-generated keys versus defining your own.
Apache HudiSeptember 17, 2025hudi.apache.org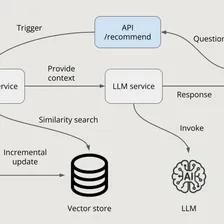
Building a RAG-based AI Recommender (2/2)
A hands-on walkthrough of a RAG product recommender, from ingesting data into Hudi to embedding, vector search, and generating answers with an LLM.
Apache HudiAIIncremental ProcessingAugust 29, 2025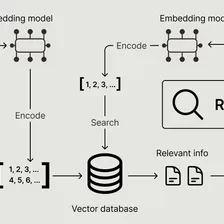
Building a RAG-based AI Recommender (1/2)
What retrieval-augmented generation is, and why fresh, well-structured lakehouse data with incremental processing is the foundation of a good RAG app.
Apache HudiAIData LakehouseIncremental ProcessingJuly 11, 2025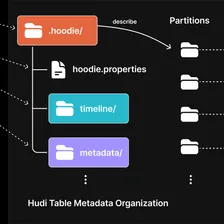
Apache Hudi does XYZ (1/10)
How Hudi's multi-modal index prunes partitions and files so query engines read only the data they need, the first post in a series on Hudi 1.0 features.
Apache HudiIndexingApache SparkJune 16, 2025
2024
Apache Hudi 2024: A Year In Review (opens in a new tab)
Reflect on and celebrate the myriad of exciting developments and accomplishments that have defined the year 2024 for the Hudi community.
Apache HudiDecember 29, 2024hudi.apache.org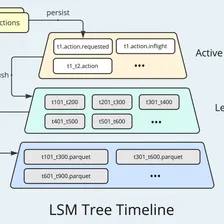
Apache Hudi: From Zero To One (10/10)
Highlights of the Hudi 1.0 release that takes the project from zero to one: the LSM timeline, non-blocking concurrency control, and new indexes.
Apache HudiData LakehouseConcurrency ControlIndexingApril 13, 2024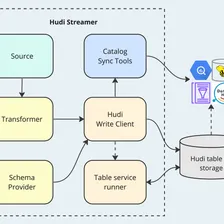
Apache Hudi: From Zero To One (9/10)
Hudi Streamer - a "Swiss Army knife" for ingestion
Apache HudiApache SparkApache KafkaMarch 1, 2024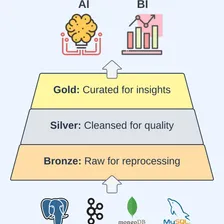
Apache Hudi: From Zero To One (8/10)
Processing only what changed in a Hudi table, through incremental queries and change data capture, to build efficient medallion pipelines.
Apache HudiIncremental ProcessingJanuary 5, 2024
2023
Apache Hudi 2023: A Year In Review (opens in a new tab)
Reflect on and celebrate the myriad of exciting developments and accomplishments that have defined the year 2023 for the Hudi community.
Apache HudiDecember 28, 2023hudi.apache.org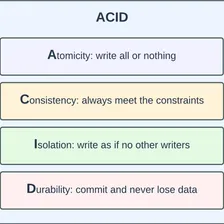
Apache Hudi: From Zero To One (7/10)
How Hudi lets multiple writers and table services run on one table at once, through MVCC and optimistic concurrency control.
Apache HudiConcurrency ControlDecember 7, 2023
Apache Hudi: From Zero To One (6/10)
How Hudi's clustering service rewrites files for better query performance, and how space-filling curves like Z-order and Hilbert sort data.
Apache HudiTable ServicesNovember 13, 2023
Record Level Index: Hudi's Blazing Fast Indexing for Large-Scale Datasets (opens in a new tab)
How Hudi's Record Level Index maps every record key to its file group in the metadata table, speeding up writes and key lookups at scale.
Apache HudiIndexingNovember 1, 2023hudi.apache.org
Apache Hudi: From Zero To One (5/10)
Introduce table services: compaction, cleaning, and indexing
Apache HudiTable ServicesIndexingOctober 19, 2023
Apache Hudi: From Zero To One (4/10)
How Hudi's writer indexes locate existing records for upserts and deletes, comparing the simple, Bloom, bucket, and record-level indexes.
Apache HudiIndexingSeptember 28, 2023
Apache Hudi: From Zero To One (3/10)
How a Hudi write works end to end, from indexing and tagging records to committing files, and the write operations Hudi offers.
Apache HudiApache SparkSeptember 15, 2023
Apache Hudi: From Zero To One (2/10)
How Hudi serves reads: the query planning flow in Spark, and the snapshot, read-optimized, time travel, and incremental query types.
Apache HudiApache SparkIncremental ProcessingSeptember 6, 2023
Apache Hudi: From Zero To One (1/10)
A first look at how Apache Hudi lays out a table on storage: the timeline, metadata files, base and log files, and how they fit together.
Apache HudiData LakehouseAugust 28, 2023
Getting Started: Incrementally process data with Apache Hudi (opens in a new tab)
How to incrementally process data with Apache Hudi, using sample code and data to illustrate several scenarios.
Apache HudiIncremental ProcessingApril 18, 2023onehouse.ai